In short, split testing shows two or more versions of a page, email or ad to a real audience and measures which one they prefer. Done properly, it turns one small change into a reliable gain. Done with a tiny sample or an early stop, it mostly produces noise dressed up as a winner.
Key Takeaways
- Confidence is rare and has to be earned. Convert, an A/B testing platform, analysed 28,304 experiments run by its own customers and found that only 20% reached the 95% statistical significance level.
- Most real wins are modest. Convert’s own recent benchmark data on completed tests found 60% delivered under 20% lift, with 39.8% landing under 10%.
- Calling a test early is expensive. The same Convert analysis found that non-winning experiments, on average, caused a 26% decrease in conversion rate when a team acted on them too soon.
- Win rates vary sharply by industry. Wingify, the company behind VWO, studied more than 1 million tests across 100,000 websites and found travel-sector variations beat their control about 40% of the time, against 60-70% in gaming and sports.
- One famous test moved tens of millions of dollars. Dan Siroker, a US presidential campaign’s analytics director, reported that a single landing page test lifted the sign-up rate from 8.26% to 11.6%, an estimated $60 million in extra donations.
In this guide
- What Most Split Testing Advice Gets Wrong
- How Split Testing Actually Works
- What Differs by What You Test
- How to Lead Each Kind of Test
- How to Measure a Split Test
- The One Rule: Never Call a Test Before It Is Powered
- A Real Case: The Button Test That Moved a Presidential Campaign
- Frequently Asked Questions About Split Testing
- Start With One Page, One Test
What Most Split Testing Advice Gets Wrong
Most split testing guides stop at definitions and a long list of tools. They rarely explain how to tell a real winner from a lucky run of traffic. That gap matters more than the tool you pick.
This guide covers the mechanics of a split test. It shows what differs between a full redesign and a small copy tweak. It shows how to read the numbers, plus the one rule that stops teams from shipping a false winner. For the wider programme this testing feeds into, see our guide to conversion rate optimization.
A few ground rules first. Convert’s figures come from its own paying customers. That is not a random sample of the whole web, so read them as one vendor’s dataset. Wingify’s million-test figure is drawn the same way, from tests it hosted. Siroker’s Obama figures are his own account of a campaign. They are widely cited but never independently re-audited. Treat every number here as the best available evidence, not a settled fact, and as a snapshot, not a permanent ranking.
How Split Testing Actually Works
A split test sends live traffic to two or more versions of something at the same time. A tool randomly assigns each visitor to a version, then tracks a single goal, such as a sign-up, a click or a sale. After enough visitors, you compare the goal rate between versions.
Randomness is what makes the comparison fair. If version A and version B saw different kinds of visitors, say morning traffic versus evening traffic, the result would reflect the traffic mix, not the change you made. Even splitting removes that risk.
A/B, Split URL and Multivariate: The Three Formats
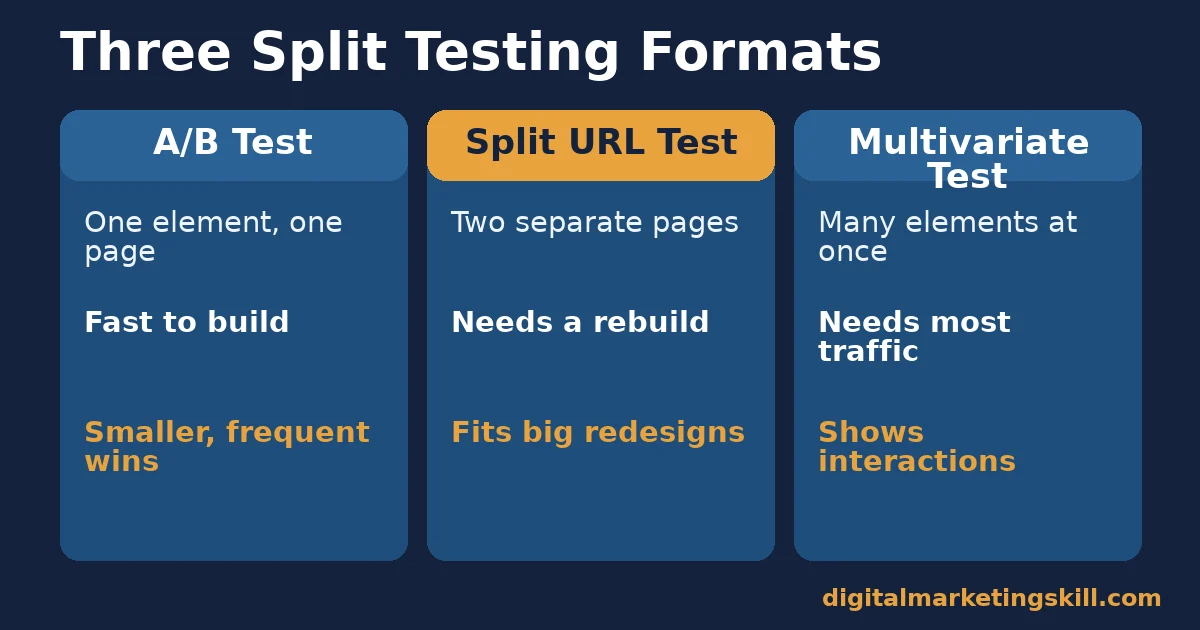
A/B testing changes one element on a single page and compares it with the original. It is the simplest format and the easiest to read.
Split URL testing compares two entirely separate pages, often with different layouts or different code. It suits bigger redesigns that would be awkward to build as one flexible page.
Multivariate testing changes several elements at once and tests every combination. Optimizely’s own explanation of multivariate testing notes that it can reveal how elements interact, but each extra combination needs more visitors, so it is usually reserved for high-traffic pages.
Why Statistical Significance Is the Real Finish Line
Statistical significance is the point where a result is unlikely to be random chance. Most teams target 95%, meaning there is roughly a 1-in-20 risk the “winner” is really a tie.
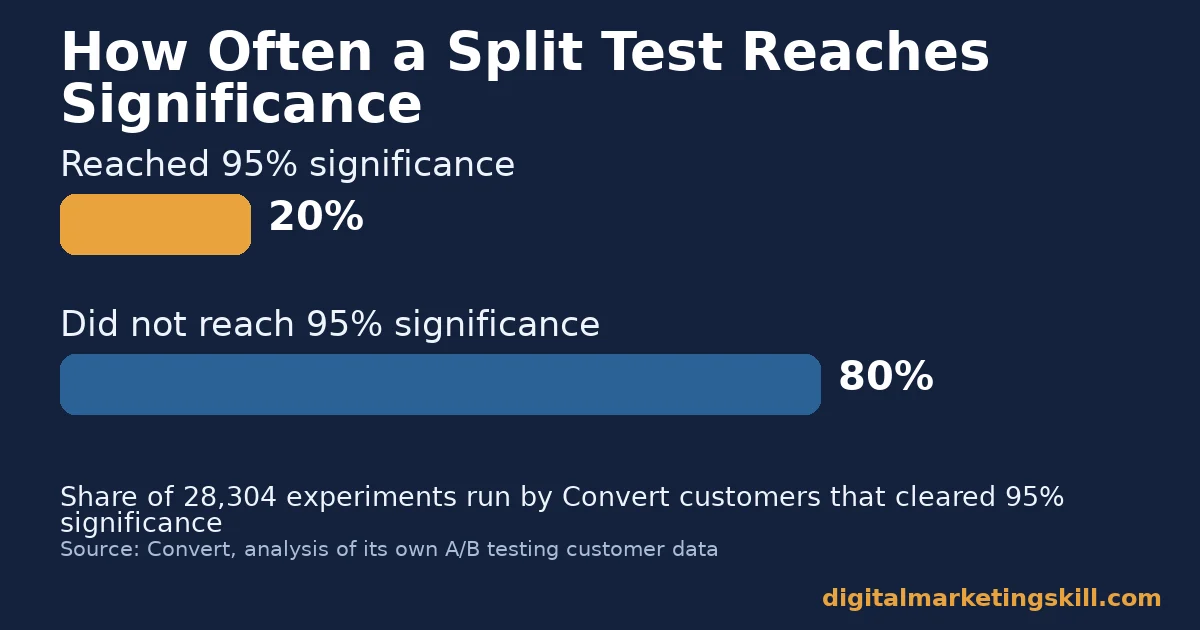
That bar is harder to clear than it looks. Convert’s analysis of 28,304 of its customers’ experiments found only 20% reached 95% significance. The rest were still running, inconclusive, or stopped before they had enough data to say anything reliable.
What Differs by What You Test
Not every split test behaves the same way. A full-page redesign and a single button-colour change need different plans, different traffic and different patience.
Full-Page Redesigns: Built for Big, Rare Swings
A redesign changes layout, copy, images and flow together. When it wins, the lift can be large, because many small frictions get fixed at once.
That size comes at a cost. You cannot tell which specific change drove the result, and a full rebuild takes real design and development time. Most teams run only a few of these a year.
Copy and Button Tests: Built for Small, Frequent Wins
A headline, a button label or a single image is quick to build and quick to test. Wins tend to be smaller, matching Convert’s finding that most completed tests land under 20% lift.
The advantage is volume. You can run many of these tests a year, and each one teaches you something specific about what your audience responds to, which a redesign cannot.
How to Lead Each Kind of Test
The two formats above need different habits once you are ready to launch. Match your approach to the type of change you are making, not the other way round.
Full-Page Redesigns: Lead With a Written Hypothesis
Write down exactly what you expect to happen and why, before launch. Something like: “Moving the price above the fold will raise sign-ups, because visitors scroll past it today.” This single sentence stops you from reading whatever story the data seems to tell afterwards.
Protect the sample. A redesign test often needs the whole page’s traffic for several weeks, so avoid running a second major test on the same page at the same time, which would muddy both results.
Copy and Button Tests: Lead With Volume and a Backlog
Keep a running backlog of small tests, ranked by how much traffic the page gets and how easy the change is to build. Work through it steadily rather than testing whatever idea came up last.
Several elements of a marketing programme are worth working through this way. Ad copy, landing pages, email subject lines, product descriptions and social captions can each carry their own small, frequent tests. Our guide to writing product descriptions covers the specific wording choices worth testing on an ecommerce page, and our guide to copywriting formulas and headlines covers the wording choices for ads and emails.
How to Measure a Split Test
A split test produces more than a single winner. Each term below is defined in one sentence, with a note on how to read it.
- Sample size. The number of visitors each version needs before the result is trustworthy. A smaller expected lift needs a bigger sample to detect it.
- Minimum detectable effect. The smallest lift you have decided is worth finding. Set this before launch, because it decides how long the test needs to run.
- Statistical significance. The likelihood the result is real rather than random, usually expressed as a percentage such as 95%.
- Conversion lift. The percentage difference in goal rate between the winning version and the original. Convert’s data on completed tests shows most real lifts sit under 20%.
- Confidence interval. The likely range around your measured lift. A wide interval means the true effect could be much smaller, or larger, than the headline number.
- Test duration. How long the test ran, usually measured in full business cycles rather than days. A short test misses weekday-versus-weekend swings in behaviour.
How to Read These Numbers Together
Start with sample size and duration. If a test has not reached its planned sample, no other number on the page means much yet. Checking in early is fine; acting on an early reading is where most false winners come from.
Once the sample is reached, read significance first, then lift, then the confidence interval. A high lift with a wide confidence interval is a result to watch, not one to ship, until a second run confirms it.
The One Rule: Never Call a Test Before It Is Powered
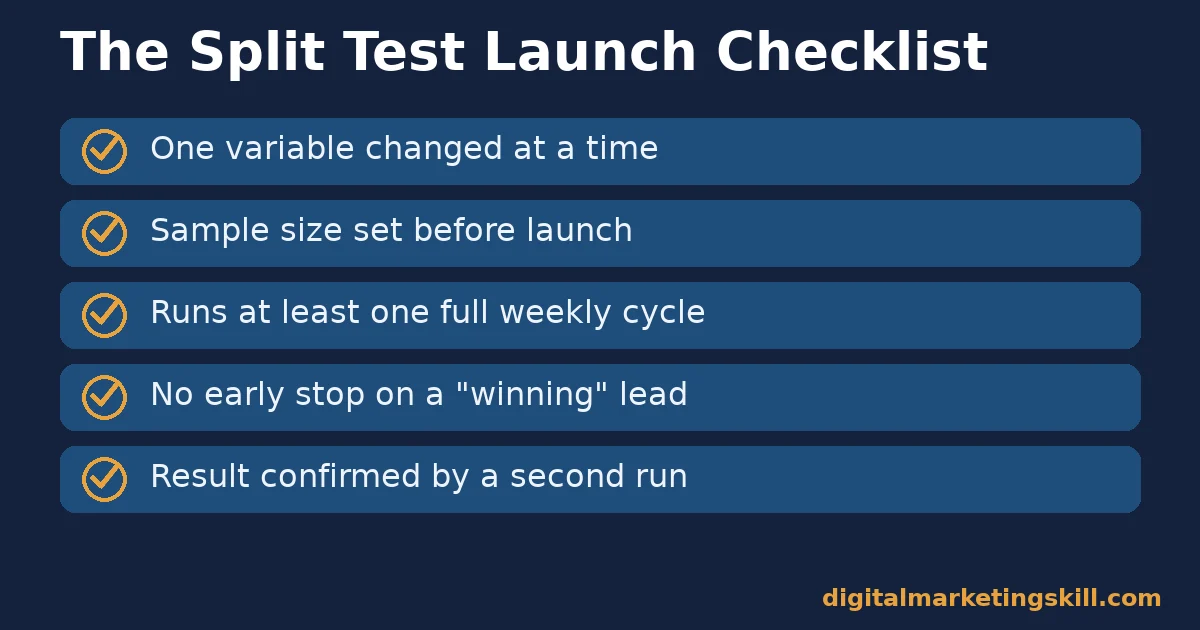
If you take one decision rule from this guide, make it this one. Decide your sample size and duration before launch, then wait for both, no matter how the early numbers look.
Here is why that discipline pays off. Convert’s analysis found that non-winning experiments, on average, caused a 26% decrease in conversion rate when teams acted on them too soon. An early, exciting-looking lead is often the exact result that reverses once the full sample arrives.
Here is an illustrative example, with invented numbers. A small software company plans a test needing 20,000 visitors per version to detect a 10% lift. After three days and 2,000 visitors, version B is “winning” by 18%. The team waits anyway. By day 21, with the full 20,000 visitors per version reached, the real lift settles at 6%, still worth shipping, but a third of the number that looked certain on day three.
A Real Case: The Button Test That Moved a Presidential Campaign
During a US presidential campaign, analytics director Dan Siroker ran a split test on the campaign’s own donation landing page. His team tried four button labels and six media options, including photos and video. Overall, visitors were randomly shown one combination.
The strongest combination paired a family photograph with a “Learn More” button. It reached a sign-up rate of 11.6%, against 8.26% for the original page. Siroker later estimated the lift brought in about 2.88 million extra email sign-ups and roughly $60 million in extra donations.
Treat the dollar figure as Siroker’s own estimate, not an audited result. Nobody has independently re-verified it against the campaign’s full books. The part worth keeping is the mechanism. A single, well-measured page change, tested on a large audience, compounded into a result far bigger than the page itself.
Frequently Asked Questions About Split Testing
What is split testing in digital marketing?
Split testing shows two or more versions of a page, email or ad to real visitors at the same time, then compares a single goal, such as sign-ups or sales, to see which version performs better.
What is the difference between split testing and A/B testing?
In everyday use, the terms are often swapped. Strictly, A/B testing changes one element on a single page, while split testing can also mean comparing two entirely separate page designs or URLs.
How long should a split test run?
Long enough to reach the sample size you calculated before launch, and across at least one full weekly cycle, so you capture both weekday and weekend behaviour. Stopping earlier risks a false winner.
What sample size do I need for a split test?
It depends on your current conversion rate and the smallest lift you want to detect. A free sample size and significance calculator from any major testing tool will give you a number before you launch, which is the point at which you should set it.
Can split testing hurt my SEO?
Not usually, if it is set up correctly. Google’s own guidance on website testing confirms running experiments does not violate its guidelines, as long as you avoid cloaking content from search engines and remove any test once it ends so a permanent duplicate page does not linger.
What tools are used for split testing?
Options range from free, limited tools built into some analytics platforms to dedicated platforms such as VWO, Optimizely and Convert, which add features like multivariate testing and audience targeting.
Is split testing worth it for a small website?
It is worth it once you have enough traffic to reach a result within a reasonable time, often a few weeks. Below that, focus on bigger, evidence-backed changes first, then start testing as traffic grows.
Start With One Page, One Test
Split testing pays off fastest when you pick one page, write a hypothesis, and wait for the sample you calculated before you draw a conclusion. Resist the pull of the early numbers; they are the most common source of a false winner.
If you want structured practice with testing and the rest of a modern marketing stack, Digital Marketing Skill Institute teaches these skills hands-on. The Master Diploma in Digital & AI Marketing is built from four AI-powered tracks. They cover social media management and advertising, lead generation and email automation, Google specialism, and WordPress and SEO. Together they total ten courses, with a Full Stack option for completing all four.
The diploma comes with unlimited 1-on-1 coaching and mentoring, plus a U.S. Project Internship with a verified U.S. Work Reference Letter. It is dual US and UK accredited and recognised in more than 100 countries.
The programme is fully online, so you can study and practise split testing from anywhere in your country. Browse more guides on the Digital Marketing Skill Institute blog, and when you are ready, apply for the Master Diploma or start from the Digital Marketing Skill Institute homepage.
Every figure in this guide was checked against its original source before publication. Figures marked as illustrative are invented examples, not real results.